
Key takeaways
A forward deployed engineer is a technical specialist embedded with a customer, building working systems on the customer’s real data instead of handing over advice.
A forward deployed sustainability engineer (FDSE) applies that model to product sustainability. The role combines LCA methodology, data engineering and product knowledge.
A static LCA report describes one product at one moment. A sustainability data system keeps answering questions as designs, suppliers and regulations change.
Decisions improve when data is granular enough to compare a supplier, a component or a production route, not just a product average.
Minviro pairs LCA practitioners with XYCLE, a cloud-native LCA platform, so companies can build the system once and scale it across products.
The problem with sustainability data that lives in PDFs
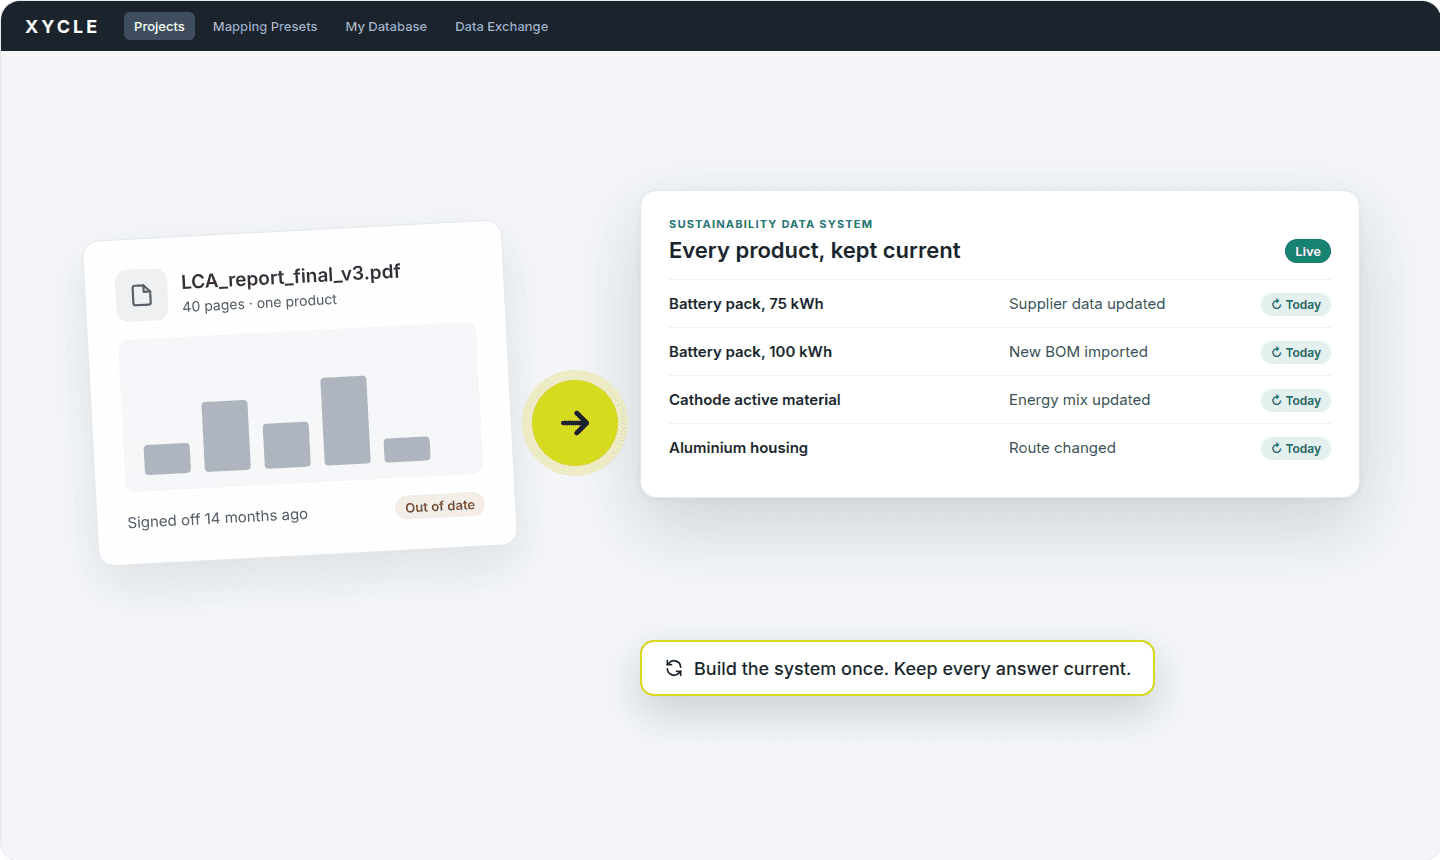
Much product sustainability work still ends in a report. A team spends weeks building a life cycle assessment, and the result is a PDF with a headline carbon footprint, a hotspot chart and a methodology appendix.
The report is accurate on the day it is signed off, then it starts to age. The bill of materials changes, a supplier switches process route, an energy mix updates, a regulation asks for a different boundary. Answering any of those questions means commissioning another study.
Reports also hide detail. The model behind a 40-page document holds thousands of data points, but the reader sees a few totals. A procurement lead comparing two suppliers, or an engineer comparing two designs, cannot query a PDF. They get an average when they needed a specific answer.
Then there is consistency. Two studies on similar products often differ because of data sources, system boundaries and method choices, not because the products differ. When each study lives in its own file, nobody can tell whether a gap between two numbers reflects the products or the modelling.
What a forward deployed engineer does
A forward deployed engineer works inside the customer’s organisation, on the customer’s real data and problems, and builds software that keeps running after the engagement ends. Palantir popularised the role, and many enterprise software and AI companies now use a version of it.
The model sits between two familiar options. A software vendor ships a generic product and leaves the customer to configure it. A consultancy studies the problem and delivers recommendations. A forward deployed engineer does neither: they build the working system, with the customer, and hand it over.
The model suits problems where the data is messy, the domain is specialist and off-the-shelf configuration falls short. Product sustainability fits that description.
The forward deployed sustainability engineer
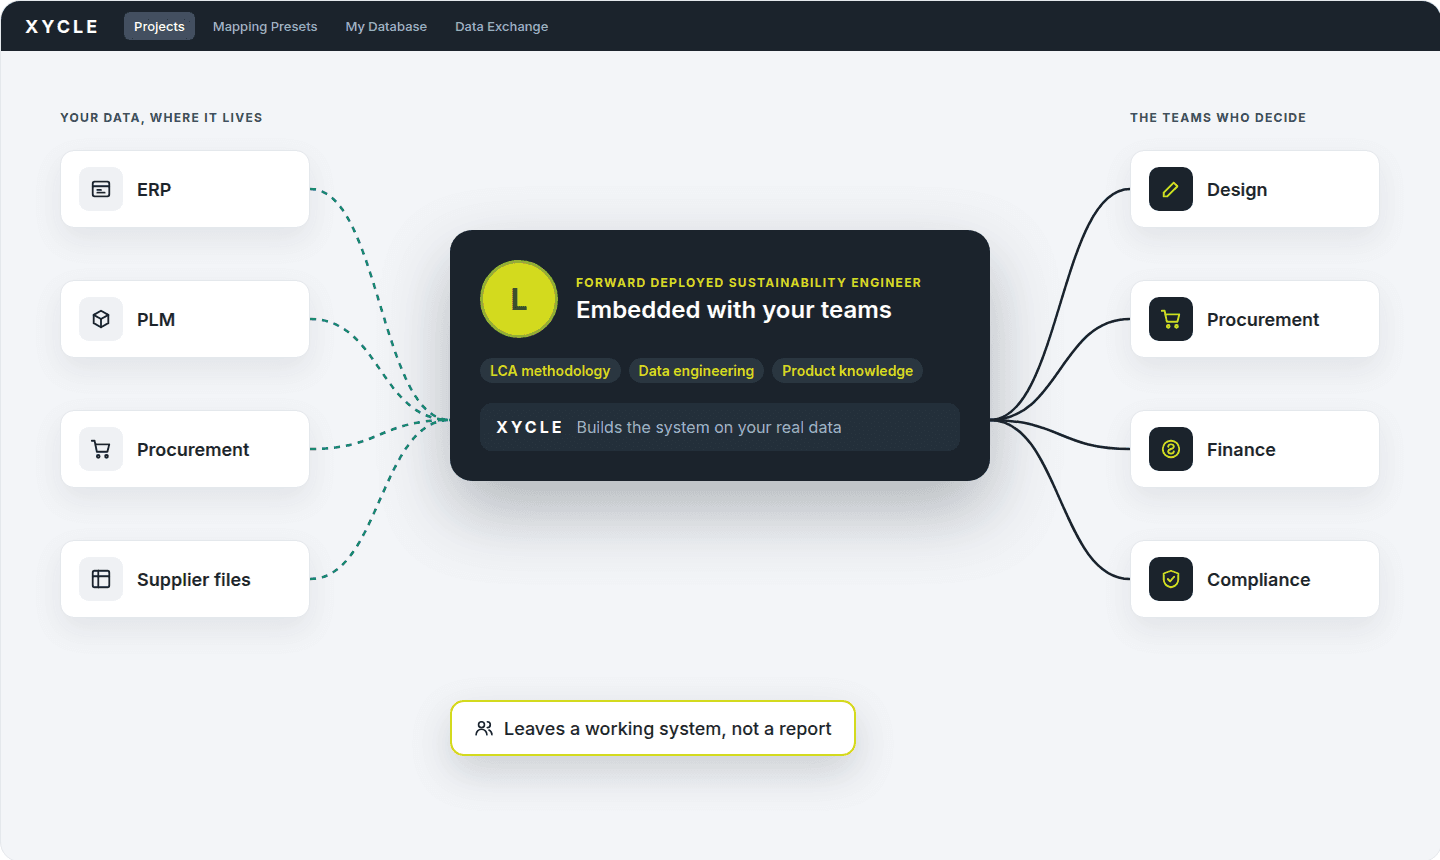
A forward deployed sustainability engineer is a technical specialist who combines LCA methodology with data engineering and works directly with product, procurement and sustainability teams. Their job is to build the data flows that turn raw product and supplier information into LCA results that update when the inputs do.
The problem has the same shape as the one forward deployed engineers were created for. The data is spread across ERP, PLM, procurement and supplier files. The methodology is specialist. The decisions need answers faster than a study cycle allows. In practice the work includes:
mapping bills of materials and supplier data to LCA models
setting up primary data collection from suppliers and checking its quality
parameterising models so a design or sourcing change reruns the numbers
connecting results to the tools where decisions get made
documenting method and data choices so results stand up to audit
The difference from a one-off study shows up in what the customer is left holding:
Static report | Sustainability data system | |
|---|---|---|
Output | One product at one point in time | Many products, kept current |
Granularity | Headline totals | Component, supplier, site and production route |
Responding to change | A new study for each question | Change an input and rerun |
Consistency | Varies by study and author | Same method and data rules on every run |
Audit trail | An appendix in a PDF | Each result traceable to its source data |
Who can use it | The sustainability team | Design, procurement, finance and compliance |
Why systems give you decision-grade granularity
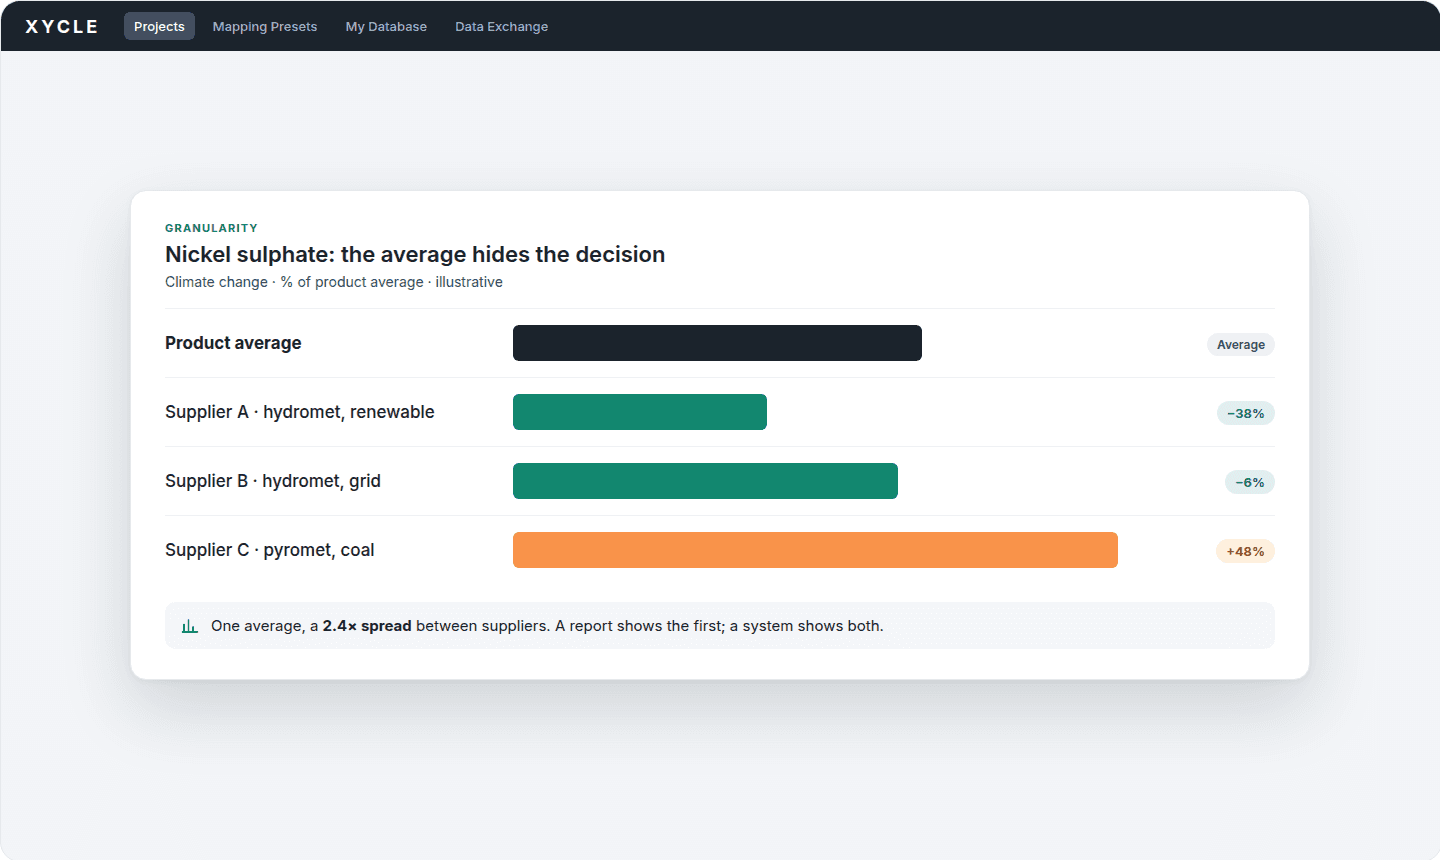
A decision needs data at the level where the decision is made. A designer choosing between two cathode chemistries needs results per material. A buyer comparing two suppliers of the same metal needs supplier-specific numbers, because the footprint of one material can differ widely with ore grade, production route and energy source.
A static report flattens all of that into an average. A system keeps the structure. Every result links to a model, every model to its data, and every data point to a source and a quality rating. That makes three things possible that a PDF cannot offer:
Comparison at the right level: component against component, supplier against supplier, route against route.
Scenarios on demand: change a recipe, a supplier or an energy mix and see the effect without a new study.
Targeted data collection: results show which inputs drive the footprint, so supplier engagement starts where it matters most.
Scale matters too. A manufacturer with hundreds of product variants cannot commission a study for each one. A system built once can cover all of them, and every new product adds to what the next one starts from.
What a sustainability data system looks like
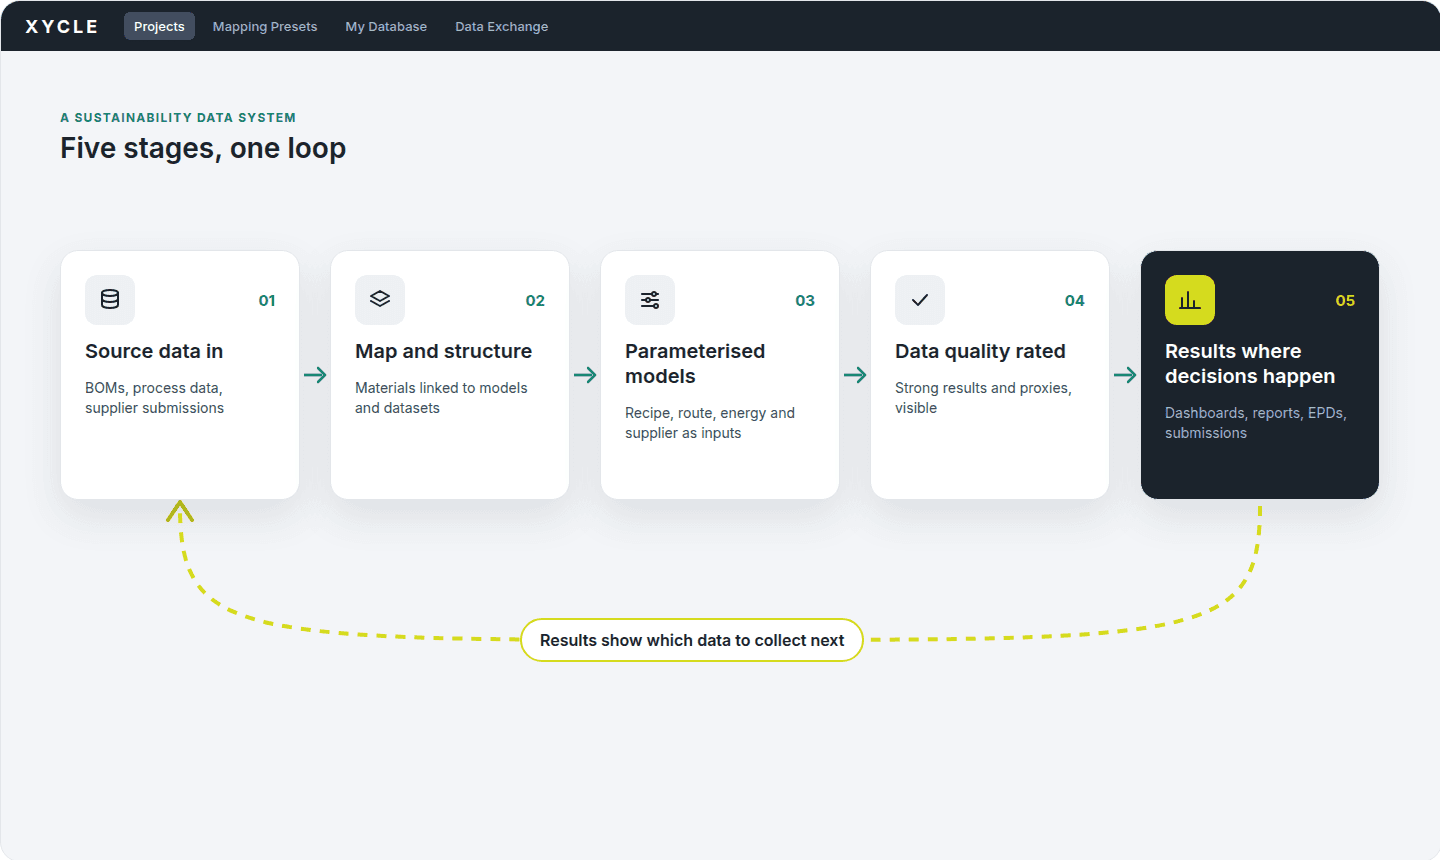
A working system has five stages, and the forward deployed sustainability engineer builds and tunes each one.
Source data comes in. Bills of materials, process data and supplier submissions are pulled from the systems where they already live.
Data is mapped and structured. Each material and process links to the right model and background dataset, with consistent units and naming.
Models run on parameters. Recipe, route, energy mix and supplier are inputs that can change without rebuilding the model.
Data quality is rated. Every input carries a rating, so teams can see where results are strong and where they rest on proxies.
Results go where decisions happen. Dashboards, reports, EPDs and regulatory submissions all draw on the same underlying model.
The loop closes when results show which inputs matter most. That tells the team where better data would change the answer, and the next round of data collection starts there.
Why Minviro and XYCLE are well positioned
Minviro has spent years doing the forward deployed work and building the software that makes it repeatable. Customers get the platform and the practitioners who built it.
Practitioners and platform together. Minviro’s consultancy team builds LCA models with customers in mining, batteries, automotive, electronics, FMCG and pharma. What the team learns on those engagements feeds back into XYCLE, so the second customer starts further ahead than the first. [CONFIRM: add one named example or case study link here]
A platform built for systems, not single studies. XYCLE is a cloud-native LCA platform. Models are parameterised, can start from templates for common materials and processes, and are reused and updated across products instead of rebuilt for each study.
Primary data on material supply chains. Minviro’s primary data work gives XYCLE models a stronger starting point than generic background datasets, with supplier-specific data where it exists. That matters most for the materials where footprints vary widely by source.
Supplier data collection in the same system. Primary data submitted by suppliers flows into the models that produce the results, with data quality ratings attached. Nothing gets re-keyed between a questionnaire and a report.
Carbon footprints you can defend. Each result traces back to its data and method, which is what makes a number usable in procurement negotiations, customer conversations and audits. [CONFIRM: add Verdantix Smart Innovators 2025 recognition, with the exact wording and a link to the report page]
Five questions to ask before you scale product sustainability
Whoever you work with, these questions separate a system from a service that produces reports.
Can I change an input and rerun a result without commissioning new work?
Can I see results by component, supplier and production route?
Does every result trace back to its source data and a quality rating?
Can suppliers submit primary data into the same system?
Can my team run it after your engineers have left?
If you want to see how this works on your own products, talk to the Minviro team or see XYCLE. [CONFIRM: link targets]

